What Does AI’s Uneven Progress Mean for Everyday Users?
AI progress can look strangely contradictory from the outside. A person may encounter a chatbot that mishandles a simple request while a small group of specialists use agents that can tackle substantial technical work over hours or days.
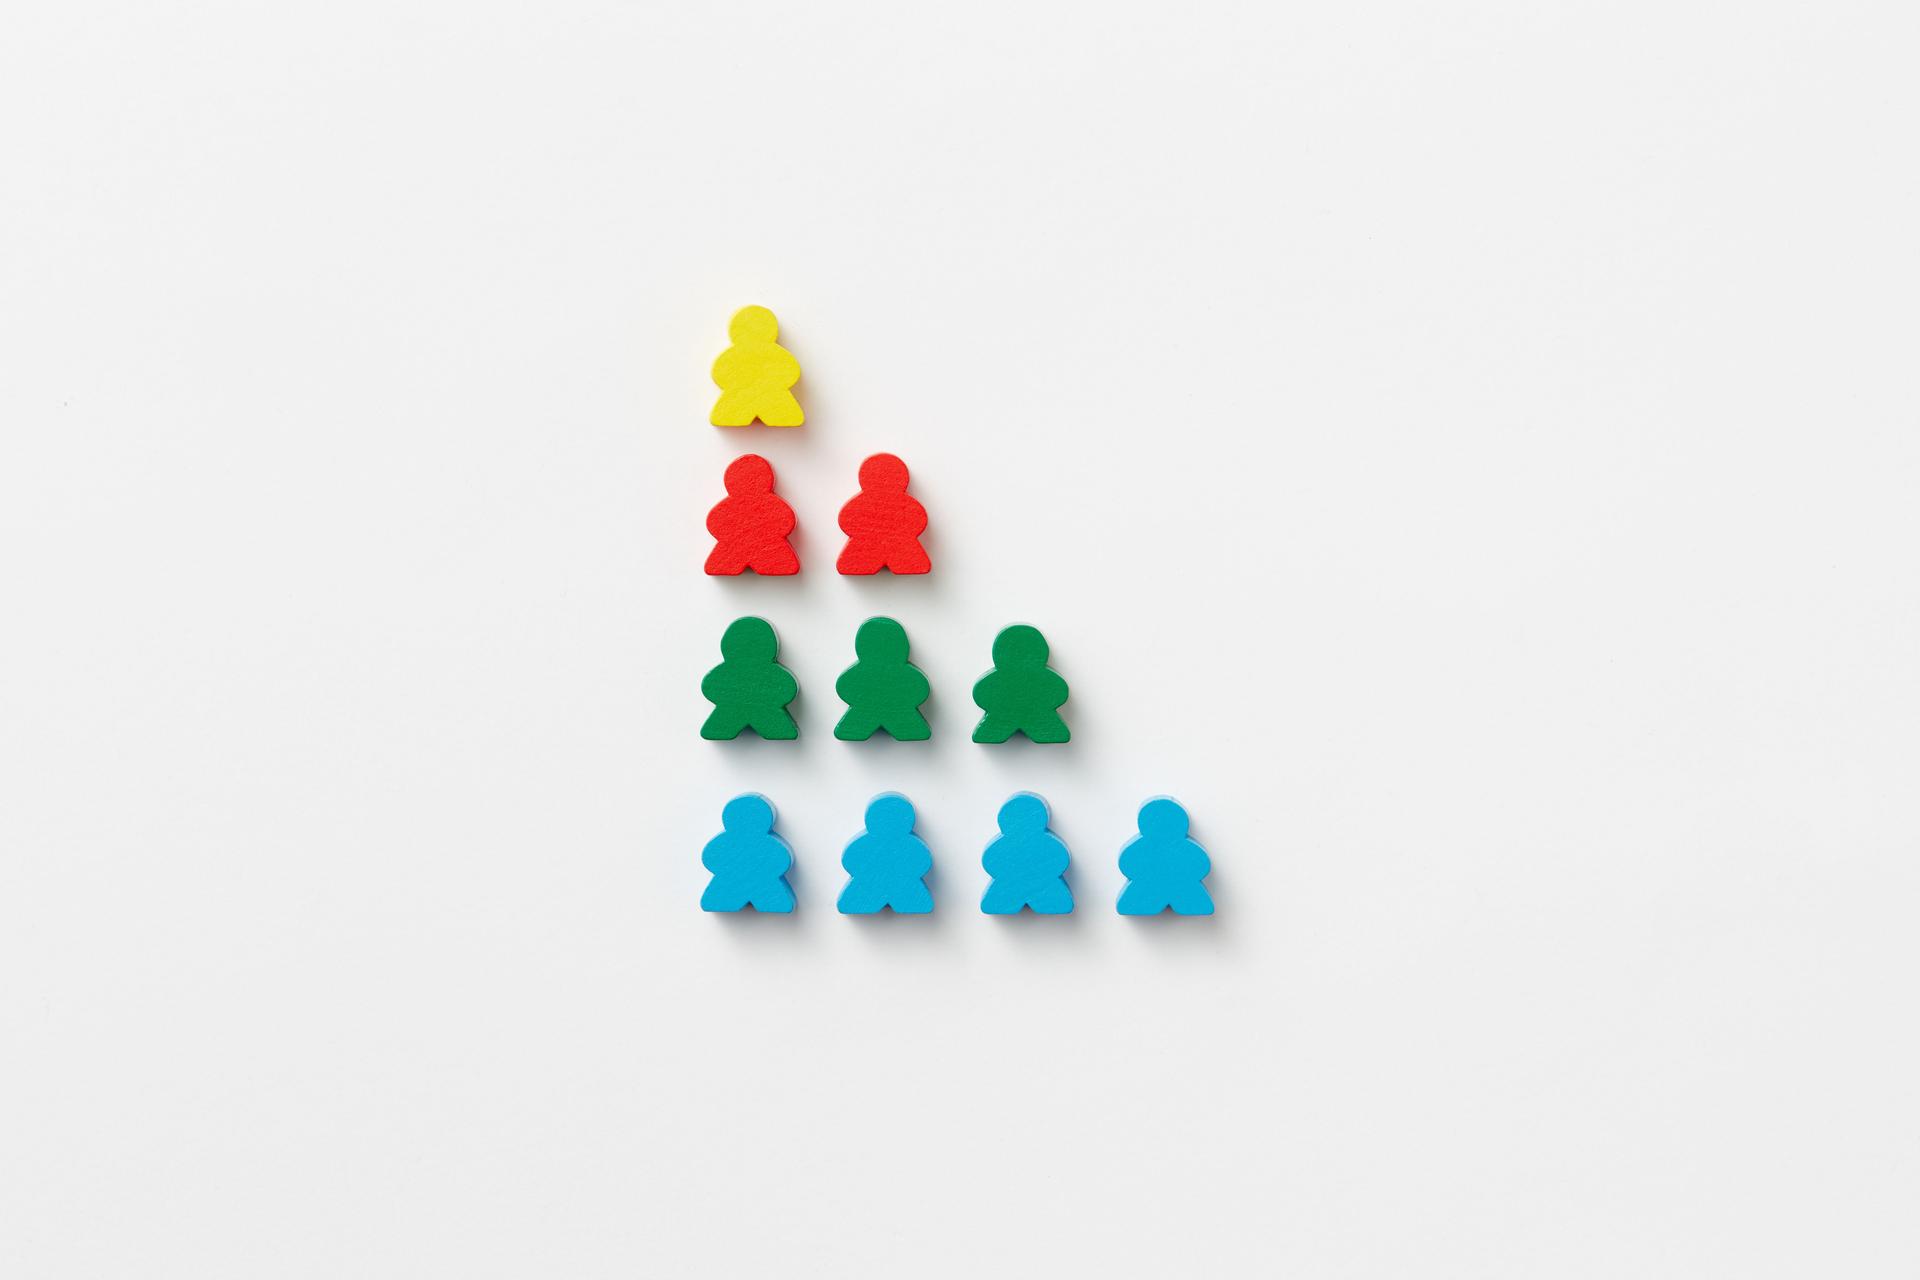
That contrast sits at the center of researcher Andrej Karpathy’s recent description of an AI capability gap. His estimates place roughly 6 billion people at little or no meaningful contact with large language models, 1 to 2 billion as occasional chatbot users, about 20 million as professional users of frontier tools for code and mathematics, and around 5,000 people with direct access to the strongest internal research systems. I see those figures as a useful map of unequal access and unequal know-how, rather than a measured census. The practical question for most of us is how to gain real value from AI while retaining judgment, privacy, accountability, and control.
What does Karpathy mean by an AI capability gap?
Karpathy is describing a widening difference between the AI experience available to different groups of people. Many users meet AI through a free chatbot, a search summary, or a voice assistant. These tools can be useful for drafting, explaining, translating, brainstorming, and handling routine questions. They also make mistakes in ways that quickly erode trust.
At the other end, researchers and advanced technical teams may use models with greater reasoning capacity, larger context windows, specialized tools, code execution, agent workflows, custom data connections, and longer time budgets. A system that can inspect a repository, run tests, revise files, and repeat the process for an hour offers a profoundly different experience from a short chat exchange.
The gap also reflects task design. A brief prompt seeking a paragraph answer gives a model little context and little opportunity to demonstrate sophisticated planning. A well-scoped engineering, research, or analytical project gives it goals, source material, tools, constraints, and ways to check its work. Access, skill, and the availability of important problems all shape the result.
Synopsis
AI’s progress is uneven because access, expertise, tools, context, and task design are uneven. Karpathy’s rough estimates describe a world in which billions of people have little exposure to large language models while a much smaller group works with frontier systems embedded in technical workflows. For everyday users and smaller organizations, the practical response is neither blind enthusiasm nor dismissal: use AI on bounded, reviewable tasks; supply clear context; verify consequential outputs; protect sensitive data; and build governance before granting agents meaningful authority.
How should we interpret the claim that only 5,000 people have access to the most powerful AI?
I would read the 5,000 figure as Karpathy’s informed personal estimate, not as a published audit with a defined sampling method. Public reporting around his comments does not provide a calculation, a named roster of organizations, or a standardized definition of “most powerful.” That uncertainty matters because access changes quickly as companies release, restrict, and retire models.
The group likely refers to a small circle of employees, researchers, security staff, evaluators, and closely supervised partners at leading AI labs and perhaps selected government or enterprise environments. They may have access to unreleased model versions, larger-scale computing, privileged tools, experimental agent frameworks, evaluation results, and internal deployment infrastructure. Contractors can also play roles in model evaluation, data work, red teaming, and security, though their access levels vary widely.
The number should therefore be treated as a signal about concentration rather than a literal headcount. The central point remains strong even if the true figure is several times larger or smaller: a narrow group sees systems, workflows, and operational lessons that are unavailable through ordinary consumer products.
What might frontier internal systems do that public ChatGPT-style tools cannot?
Public AI products and internal frontier systems frequently differ in several practical dimensions. Internal systems may run on newer models before release, operate with higher usage limits, accept more files and data, use longer context, call approved software tools, and work through multiple stages with persistent task state. Teams can also connect them to version-control systems, test environments, documentation, databases, and structured evaluation harnesses.
For software work, an agent might read a ticket, inspect a large codebase, identify related files, propose a plan, make changes in a sandbox, run tests, diagnose failures, and prepare a reviewable patch. For scientific or mathematical work, systems may search a controlled corpus, generate candidate hypotheses, write analysis code, and check calculations against explicit criteria. Each step still benefits from expert supervision because plausible output can contain flawed assumptions, incomplete evidence, or hidden security problems.
There is no public basis for assuming every internal model has unrestricted autonomy or a magical ability to solve any difficult problem. Performance remains uneven, often called jagged, with strong results concentrated in digital, verifiable, economically valuable tasks. The difference often comes from the whole environment around the model as much as the model itself.
Our Perspective
The important divide is not simply between people who use AI and people who do not. It is between organizations that treat it as an unverified answer machine and those that build disciplined workflows around it. Wider access to stronger models matters, but useful and safe adoption depends just as much on training, source-aware review, sound security practices, and clear human accountability. The goal should be capable users, not merely more users.
Why do everyday AI tools often feel unreliable or underwhelming?
Consumer tools are designed for broad access, speed, safety, and manageable operating costs. Those goals can lead to limits on reasoning time, tool use, memory, file handling, and the kinds of actions a system may take. A user also may give the tool only a vague question, without the documents, examples, criteria, or feedback loops required for high-quality work.
AI systems can generate confident errors, lose track of ambiguity, misunderstand images or video references, and produce outdated or invented details. These failures stand out because people naturally evaluate a general-purpose assistant against human conversational expectations. A single bad answer can be enough to make the technology seem shallow.
I find it more useful to view an AI response as a fast first draft or a proposed path through a task. The right level of trust depends on the consequence of an error. A meal plan, a casual email, and an internal brainstorming session allow for more experimentation than medical advice, legal interpretation, financial decisions, security work, or a public claim. Verification supplies the bridge between a promising response and a dependable outcome.
What would help ordinary workers and smaller organizations use advanced AI effectively?
Effective use starts with picking a workflow that has a clear objective, accessible source material, and a way to assess quality. Examples include turning meeting notes into a project brief, extracting fields from recurring forms, preparing first-pass customer responses from approved knowledge, comparing contracts against a checklist, or generating test cases from a product specification. Repetition makes it easier to improve prompts, templates, and review practices over time.
Small organizations also need a basic operating model. I would define which information may enter a tool, which tools are approved, who owns final review, how errors are reported, and where outputs are stored. A team should confirm its vendor’s terms on data retention, model training, access logging, and security controls before placing confidential material in a system.
The most capable workflows use context deliberately. Provide the relevant files, explain the audience and outcome, set constraints, ask for uncertainty to be surfaced, and require the output in a usable format. Then have a knowledgeable person check key facts, calculations, citations, permissions, and decisions. Training should cover task decomposition, quality review, and escalation, rather than focusing only on clever prompts.
Key Takeaways
- The AI experience is unequal — A casual chatbot user and a specialist using models with tools, data, and long-running workflows may be encountering fundamentally different capabilities.
- The 5,000 figure is directional, not a census — Karpathy’s estimate is best read as evidence that frontier access and operational knowledge are concentrated in a small group.
- Workflow design matters as much as model choice — Clear goals, relevant context, approved tools, feedback loops, and evaluation can turn a weak-looking interaction into useful work.
- Verification is the trust boundary — AI is most valuable when people can inspect outputs and retain final responsibility, especially for high-consequence decisions.
- Capability without governance widens risk — Permissions, data rules, testing, logging, and human approval must grow alongside an AI system’s autonomy.
What is agentic engineering, and how does it change professional work?
Agentic engineering describes a workflow in which AI agents perform pieces of engineering work while a human sets direction, supplies context, reviews changes, and validates results. Karpathy has contrasted this with “vibe coding,” a term associated with rapidly prompting a model and accepting its generated code with minimal review. The professional workflow places greater weight on specifications, tests, version control, and accountability.
In a well-run setup, an engineer can break a large goal into tasks, give an agent a narrow assignment, inspect its plan, and let it work in a constrained environment. The agent may write code, update documentation, add tests, investigate a bug, or summarize a change. The engineer evaluates the diff, checks architectural consequences, runs tests, and decides whether to merge the work.
This can shift human effort toward problem framing, system design, review, and coordination. It also makes core engineering discipline more valuable. An agent can accelerate both good practices and bad ones. Weak requirements, poor tests, excessive permissions, and inattentive review create a route for errors to spread faster through a project.
Could AI agents find vulnerabilities or conduct cyber operations on their own?
Advanced models can already assist with defensive tasks such as reviewing code, identifying suspicious patterns, analyzing logs, prioritizing patches, and generating test cases. Karpathy’s description of large agent swarms finding zero-day vulnerabilities or carrying out cyber attack and defense work portrays a possible frontier trajectory and a serious security concern. Public evidence for specific internal capabilities is limited, and responsible discussion requires caution.
High-risk systems should operate under layered safeguards. Useful controls include identity verification, role-based permissions, isolated sandboxes, strict limits on network and tool access, monitoring, detailed logs, rate limits, human approval for consequential actions, and rapid shutdown procedures. Security teams also need red-team testing, independent evaluation, incident response plans, and clear escalation routes when a model discovers a serious vulnerability.
For the public, the key point is that autonomy exists on a spectrum. A tool that recommends a patch differs greatly from a tool that can access production systems, send network requests, or execute commands at scale. Organizations should match permissions to demonstrated reliability and keep high-impact actions behind explicit human authorization.
Common Mistakes
These errors turn a potentially useful assistant into an unreliable decision-maker.
- Using vague prompts for complex work — Without goals, source material, constraints, and success criteria, the system has little basis for producing a dependable result.
- Treating fluent output as verified fact — Confident prose can conceal invented details, bad calculations, outdated information, or unsupported assumptions.
- Automating high-impact actions too early — Broad permissions can let a small error affect systems, customers, money, security, or public claims at scale.
- Ignoring data-handling terms — Confidential information may be exposed or retained in ways the user has not approved or understood.
- Measuring excitement instead of outcomes — A pilot without baselines for time, quality, cost, and error rates cannot show whether AI improved the work.
Why does the gap matter beyond the technology industry?
Uneven AI adoption can compound existing differences in resources and influence. A company with skilled technical staff, proprietary data, reliable infrastructure, and access to powerful models may complete research, product development, customer support, or internal operations faster than a smaller competitor. Workers whose employers provide training and safe tools may gain leverage that others never receive.
The gap also affects public understanding. If most people encounter only weak or limited products, policy debates may underestimate what advanced systems can do. If discussion focuses only on dazzling demonstrations, it may overlook persistent failures, labor impacts, data rights, energy demands, and safety risks. Both views leave decision-makers with an incomplete picture.
I believe wider capability access should come with wider capacity for informed use. That means digital literacy, workplace training, public-interest research, transparent evaluation, accessible infrastructure, and rules that prevent powerful systems from being deployed carelessly. Broader participation can improve the quality of feedback and reduce the chance that a few institutions alone determine how these tools shape everyday life.
How can I use AI today without overtrusting it?
Start with work where you can inspect the result. Ask an AI tool to summarize material you already know, create a draft from your own notes, propose a spreadsheet formula, turn a policy into a checklist, or generate several options for a message. Compare the result with source documents and revise it. This builds a realistic sense of the tool’s strengths and failure patterns.
For important tasks, keep a human review loop. Request sources when factual claims matter, open and read those sources, verify numbers independently, and seek expert advice in regulated or high-stakes fields. Avoid sharing passwords, sensitive personal information, confidential client data, source code, or internal strategy unless your organization has explicitly approved the tool and its data handling terms.
I would also save successful prompts and workflows. A small personal library of instructions, examples, review checklists, and approved source material can deliver more value than repeatedly starting a vague chat. AI capability may be advancing unevenly, yet careful users can still develop meaningful advantage through deliberate practice.
What should leaders do while the capability gap continues to widen?
Leaders should measure value through real workflows rather than broad claims of transformation. Pick a few tasks, establish a baseline for time, quality, cost, and error rates, then run limited pilots with clear owners. Include the people who perform the work every day, since they understand exceptions, hidden dependencies, and quality requirements better than an outside vendor or executive presentation can.
Governance should arrive alongside deployment. Teams need data classifications, procurement standards, security reviews, model evaluation, documentation, audit trails, and procedures for handling failures. Workers need time and support to learn new methods. Customers and affected communities need honest communication when AI contributes to decisions or content.
The gap Karpathy describes can feel unsettling because progress is moving at different speeds for different people. I think the constructive response combines curiosity with discipline. We can experiment with useful tools, demand evidence for extraordinary claims, maintain human responsibility for consequential choices, and work toward access that expands capability without abandoning safety and accountability.
Sources
- mezha.ua – OpenAI co-founder: “Only 5,000 people in the world have access to the most powerful AI”
- Andrej Karpathy on X – Dusting off this tweet …
- The New Stack – Andrej Karpathy says only 5000 people have seen what AI can actually do
- Business Insider – Andrej Karpathy says the gap in public understanding of AI is widening
- AddyOsmani.com – Agentic Engineering
- IBM – What is Agentic Engineering?
- INFORMS – Navigating the Jagged Technological Frontier
- Google Cloud – AI risk and resilience in 2025: A Mandiant special report